The Signal and the Noise Why Information Extraction is the Secret Engine of Modern Intelligence
We are currently drowning in a sea of words, yet we are starving for actual knowledge. Imagine being handed a 500-page legal contract and told you have exactly ten seconds to find every mention of a “liability clause” and the associated monetary figures. To a human, that’s an impossible nightmare. To a machine equipped with information extraction, it’s just another Tuesday.
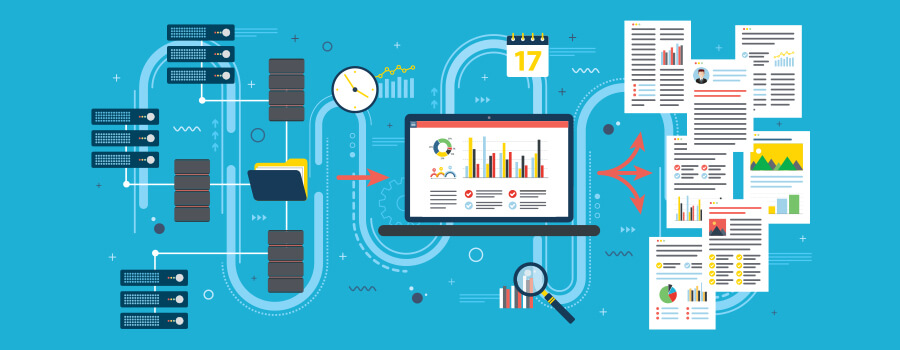
Most people confuse “searching” with “extracting.” But there is a massive difference. Searching finds the document; information extraction finds the truth inside the document. It is the bridge between a messy, unorganized pile of text and a clean, actionable spreadsheet that actually helps you make a decision.
Beyond the Search Bar: What is Information Extraction?
At its core, information extraction (IE) is the automated process of pulling specific, pre-defined bits of data from unstructured sources—like emails, PDFs, or social media posts—and turning them into a structured format.
Think of it like this: If the internet is a giant, disorganized soup of letters, IE is the strainer that catches only the carrots and the beef while letting the broth flow away. It doesn’t just read the text; it identifies entities (people, places, companies), relations (who works where), and events (what happened when).
The Three Pillars of Extraction
-
Named Entity Recognition (NER): Identifying that “Apple” in a sentence refers to the tech giant, not the fruit you had for breakfast.
-
Relation Extraction: Understanding that “Elon Musk” is the “CEO” of “Tesla.” It’s about the invisible lines connecting the dots.
-
Event Extraction: Pinpointing that a “Merger” happened on “October 12th” involving “Company A” and “Company B.”
Reality Check: Extraction is Not Summarization
There is a major misconception that if you use an AI to summarize a document, you have performed information extraction. Reality check: You haven’t. Summarization gives you a “vibe” or a shorter version of the story. IE gives you the data. A summary tells you, “The company had a bad quarter.” Extraction tells you, “Revenue: -$2.4M; Date: Q3 2025; Reason: Supply Chain.” One is a narrative; the other is a data point. If you want to build a database, you need extraction, not just a summary.
The Editorial Opinion: The “Context” Crisis
Here is my take on the current state of the industry: We are getting too good at finding names, but we are still mediocre at understanding intent. The “Information Extraction” tools of five years ago were rigid and broke the moment a sentence became sarcastic or complex.
Modern IE, powered by LLMs (Large Language Models), is much better, but we are entering a dangerous phase where we trust the machine’s “extraction” too blindly. If the AI extracts a “10% discount” but misses the word “unless,” your business logic fails. The future of IE isn’t just about “pulling data”—it’s about “verifying context.” We need to move from “What was said?” to “What was meant?”
Why Your Business is Already Using It (Even if You Don’t Know It)
You might think IE is some high-level academic concept, but it is likely running in the background of your favorite tools right now:
-
Email to Calendar: When Gmail asks if you want to add a flight to your calendar because it “saw” a confirmation email—that is information extraction in action.
-
Customer Support: AI bots that scan your angry tweet and immediately categorize it as a “billing issue” and tag your “account number” are performing real-time IE.
-
Financial Auditing: Banks scan millions of transactions to extract patterns of fraud that no human eye could ever catch in time.
The “Quiet” Challenge: Data Variety

A thing that is rarely discussed in flashy tech keynotes is the “PDF Problem.” Most of the world’s most valuable information is trapped in messy, poorly formatted PDFs or scanned images. Doing information extraction on a clean Wikipedia page is easy. Doing it on a crumpled, handwritten invoice from a supplier in another country is where the real battle is won. This is where OCR (Optical Character Recognition) meets IE, and it’s one of the most difficult engineering hurdles today.
Practical Steps: How to Implement IE Without a PhD
If you are looking to harness the power of information extraction for your own projects, don’t start by building a model from scratch.
-
Use Pre-trained API’s: Tools like AWS Comprehend, Google Cloud Natural Language, or spaCy offer incredible NER and relation extraction out of the box.
-
Define Your Schema First: The machine can’t find what you haven’t defined. Do you need “Dates”? “Prices”? “Names of Competitors”? Be specific before you run the code.
-
Human-in-the-Loop: Especially for YMYL (Your Money Your Life) industries like law or health, always have a human spot-check the extracted data. Use the AI to do the 90% of the heavy lifting, and let the human do the 10% of high-stakes verification.
Conclusion: Turning the Mess into Meaning
We don’t have an information problem; we have a “meaning” problem. Information extraction is the only way we can keep up with the sheer volume of digital noise we produce every day. It turns the chaotic “noise” of the internet into the “gold” of structured insights.
As we move forward, the most successful people won’t be those who have the most data—they will be those who have the best strainers to catch the things that actually matter.